Inference without explicit message update rules
RxInfer utilizes the ReactiveMP.jl package as its inference backend. Typically, running inference with a custom factor node requires you to declare the node with the @define_factor_node macro and to define its message update rules with the @define_message_update_rule macro. For background on what rules are and how they work, see Understanding Rules. Detailed instructions on implementing rules can be found in this section of the documentation. In this tutorial, we explore an alternative approach: inference with a fallback message update rule for custom factor nodes, which only needs BayesBase.logpdf and BayesBase.insupport for the node's distribution, without any rules.
In the context of message-passing based Bayesian inference, custom message update rules enhance precision and efficiency. These rules leverage the specific mathematical properties of the model's distributions and relationships, leading to more accurate updates and faster convergence. By incorporating domain-specific knowledge, custom rules improve the robustness and reliability of the inference process, particularly in complex models where default rules may be inadequate or inefficient.
A simple prior-likelihood model
We start a simple model with a hidden variable p and observations y. Later in the tutorial we explore more advanced use-cases. In this particular case we assume that p follows a prior distribution and y are drawn from a likelihood distribution. The model can be defined as follows:
using RxInfer

@model function simple_model(y, prior, likelihood)
    p ~ prior
    y .~ likelihood(p)
end
Node specifications
Next, we define structures for both the prior and the likelihood. Let's start with the prior. Assume that the p parameter is best described by a Beta distribution. We can define it as follows:
The Distributions.jl package already provides a fully-featured implementation of Beta and Bernoulli distributions, including functions like logpdf and support checks. The example below redefines the Beta distribution structure and related functions solely for illustrative purposes. In practice, you often won't need to define these distributions yourself, as many of them has already been included in Distributions.jl.
using Distributions, BayesBase

struct BetaDistribution{A, B} <: ContinuousUnivariateDistribution
    a::A
    b::B
end

# Reuse `logpdf` from `Distributions.jl` for illustrative purposes
BayesBase.logpdf(d::BetaDistribution, x) = logpdf(Beta(d.a, d.b), x)
BayesBase.insupport(d::BetaDistribution, x::Real) = 0 <= x <= 1
Next, we assume that y is a discrete dataset of true and false values. The logical choice for the likelihood distribution is the Bernoulli distribution.
struct BernoulliDistribution{P} <: DiscreteUnivariateDistribution
    p::P
end

# Reuse `logpdf` from `Distributions.jl` for illustrative purposes
BayesBase.logpdf(d::BernoulliDistribution, x) = logpdf(Bernoulli(d.p), x)
BayesBase.insupport(d::BernoulliDistribution, x) = x === true || x === false
The next step is to declare these structures as factor nodes:
@define_factor_node(node = BetaDistribution, type = Stochastic, interfaces = [:out, :a, :b])
@define_factor_node(node = BernoulliDistribution, type = Stochastic, interfaces = [:out, :p])
When declaring a node for a custom distribution, you must follow a specific interface ordering. The first interface is always out, which represents a sample in the logpdf function. All remaining interfaces must match the parameters of the distribution's constructor in the exact same order. For example, for the BetaDistribution, the node function is (out, a, b) -> logpdf(BetaDistribution(a, b), out). The declaration defines this function, nodefunction, which the fallback evaluates:
f = MessagePassingRulesBase.nodefunction(BernoulliDistribution)
f(out = true, p = 0.3) ≈ logpdf(Bernoulli(0.3), true)trueAlthough Beta is a conjugate prior for the parameter of the Bernoulli distribution, ReactiveMP and RxInfer are unaware of this and cannot exploit this information. To utilize conjugacy, refer to the custom node creation section of the documentation.
Generating a synthetic dataset
Previously, we assumed that our dataset consists of discrete values: true and false. We can generate a synthetic dataset with these values as follows:
using StableRNGs, Plots

hidden_p    = 1 / 3.1415 # a value between `0` and `1`
ndatapoints = 1_000      # number of observations
dataset     = rand(StableRNG(42), Bernoulli(hidden_p), ndatapoints)

bar(["true", "false"], [ count(==(true), dataset), count(==(false), dataset) ], label = "dataset")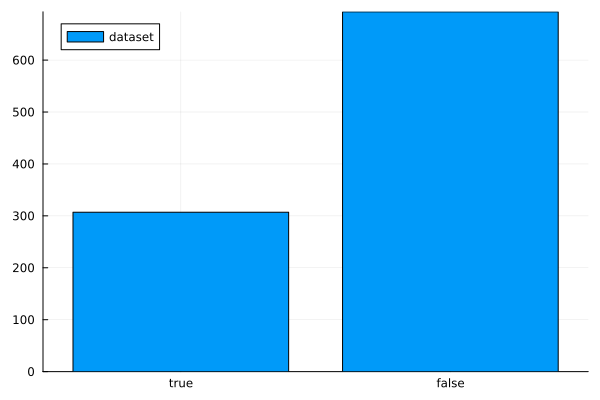
Inference with a rule fallback
Now, we can run inference with RxInfer. Since explicit rules for our nodes have not been defined, we can instruct the ReactiveMP backend to use a fallback where no rule fits, with the rulefallback option. Refer to the rule fallbacks page of MessagePassingRulesBase for how fallbacks work. In this example, we use NodeFunctionRuleFallback, which uses the logpdf of the stochastic node to approximate messages: its message towards an interface is the node's log-density as a function of that interface, with every other input collapsed to its mean.
NodeFunctionRuleFallback employs a simple approximation for outbound messages, which may significantly degrade inference accuracy. Whenever possible, it is recommended to define proper message update rules.
To complete the inference setup, we must define an approximation method for posteriors using the @constraints macro. We will utilize the ExponentialFamilyProjection library to project an arbitrary function onto a member of the exponential family. More information on ExponentialFamilyProjection can be found in the Non-conjugate Inference section and in its official documentation.
using ExponentialFamilyProjection

@constraints function projection_constraints()
    # Use `Beta` from `Distributions.jl` as it is compatible with the `ExponentialFamilyProjection` library
    q(p) :: ProjectedTo(Beta)
end
projection_constraints (generic function with 1 method)With all components ready, we can proceed with the inference procedure:
result = infer(
    model = simple_model(prior = BetaDistribution(1, 1), likelihood = BernoulliDistribution),
    data = (y = dataset, ),
    constraints = projection_constraints(),
    options = (
        rulefallback = NodeFunctionRuleFallback(),
    )
)
Inference results:
Posteriors | available for (p)
For rulefallback = NodeFunctionRuleFallback() to apply, the node must be declared as Stochastic without interface groups, and calling the node with its inputs, as BernoulliDistribution(p), must return an object with a logpdf. The fallback does not apply to a member of a group or to an input that is a joint marginal, and a rule of the node, where one fits, takes precedence over it.
Result analysis
We can perform a simple analysis and compare the inferred value with the hidden value used to generate the actual dataset:
using Plots, StatsPlots
plot(result.posteriors[:p], label = "posterior of p", fill = 0, fillalpha = 0.2)
vline!([ hidden_p ], label = "hidden p")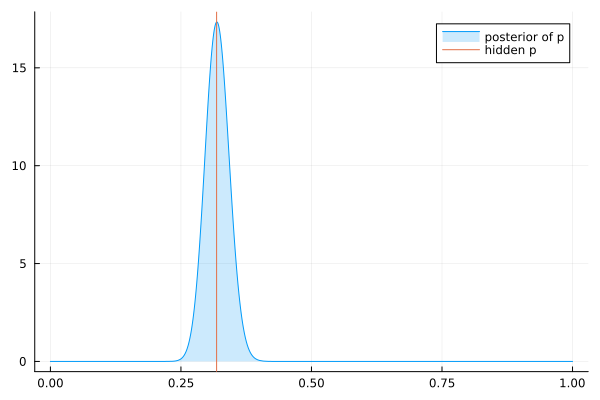
As shown, the estimated posterior is quite close to the actual hidden value of p used during the inference procedure.
Fusing deterministic transformations with stochastic nodes
One of the limitations of the NodeFunctionRuleFallback implementation is that it does not support Deterministic or Delta nodes. However, it is possible to combine a deterministic transformation with a stochastic node, such as Gaussian. For instance, consider a dataset drawn from the Normal distribution, where the mean parameter has been transformed by a known function, and the true hidden variable is h.
using ExponentialFamily, Distributions, Plots, StableRNGs

hidden_h = 2.3
hidden_t = 0.5

known_transformation(h) = exp(h)

hidden_mean = known_transformation(hidden_h)
ndatapoints = 50
dataset = rand(StableRNG(42), NormalMeanPrecision(hidden_mean, hidden_t), ndatapoints)

histogram(dataset; normalize = :pdf)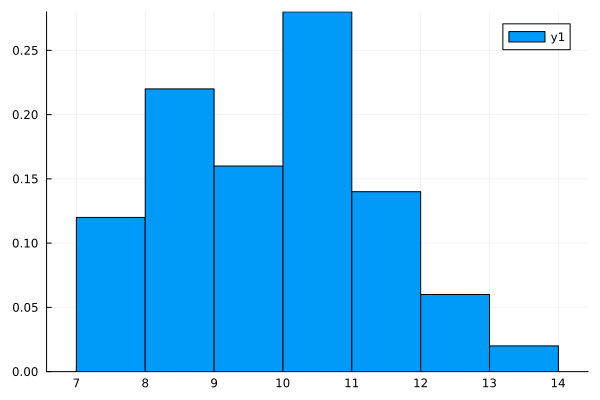
The model can be defined as follows:
using RxInfer

@model function mymodel(y, prior_h, prior_t)
    h ~ prior_h
    t ~ prior_t
    y .~ Normal(mean = known_transformation(h), precision = t)
end
Inference in this model is challenging because the known_transformation function is explicitly used as a factor node, requiring special approximation rules. These rules are covered in a separate section. Here, we demonstrate a different approach that modifies the model structure to run inference without needing to approximate messages around a deterministic node.
First, we define our custom transformed Normal distribution:
using BayesBase

struct TransformedNormalDistribution{H, T} <: ContinuousUnivariateDistribution
    h::H
    t::T
end

# We integrate the `known_transformation` within the `logpdf` function
# This way, it won't be an explicit factor node but hidden within the `logpdf` of another node
BayesBase.logpdf(dist::TransformedNormalDistribution, x) = logpdf(NormalMeanPrecision(known_transformation(dist.h), dist.t), x)
BayesBase.insupport(dist::TransformedNormalDistribution, x) = true

@define_factor_node(node = TransformedNormalDistribution, type = Stochastic, interfaces = [:out, :h, :t])
Next, we tweak the model structure:
@model function mymodel(y, prior_h, prior_t)
    h ~ prior_h
    t ~ prior_t
    y .~ TransformedNormalDistribution(h, t)
end
We use the following priors, constraints, and initialization:
using ExponentialFamilyProjection

prior_h = LogNormal(0, 1)
prior_t = Gamma(1, 1)

constraints = @constraints begin
    q(h, t) = q(h)q(t)
    q(h) :: ProjectedTo(LogNormal)
    q(t) :: ProjectedTo(Gamma)
end

initialization = @initialization begin
    q(t) = Gamma(1, 1)
end
Initial state:
q(t) = Gamma{Float64}(α=1.0, θ=1.0)
The ProjectedTo macro has a parameters field that allows for different hyperparameters, which may improve accuracy or convergence speed. Refer to the ExponentialFamilyProjection documentation for more information.
Inference with a rule fallback
Now we are ready to run the inference procedure:
result = infer(
    model = mymodel(prior_h = prior_h, prior_t = prior_t),
    data = (y = dataset,),
    constraints = constraints,
    initialization = initialization,
    iterations = 50,
    options = (
        rulefallback = NodeFunctionRuleFallback(),
    )
)
Inference results:
Posteriors | available for (h, t)
Result analysis
Finally, let's plot the resulting posteriors for each VMP iteration:
@gif for (i, q) in enumerate(zip(result.posteriors[:h], result.posteriors[:t]))
    p1 = plot(1:0.01:3, q[1], label = "q(h) iteration $i", fill = 0, fillalpha = 0.2)
    p1 = vline!([hidden_h], label = "hidden h")

    p2 = plot(0:0.01:1, q[2], label = "q(t) iteration $i", fill = 0, fillalpha = 0.2)
    p2 = vline!([hidden_t], label = "hidden t")

    plot(p1, p2)
end fps = 15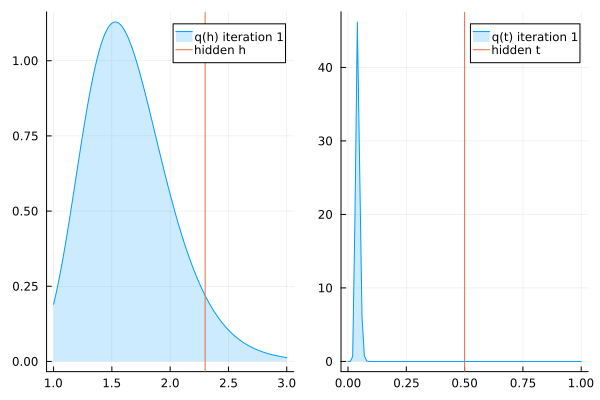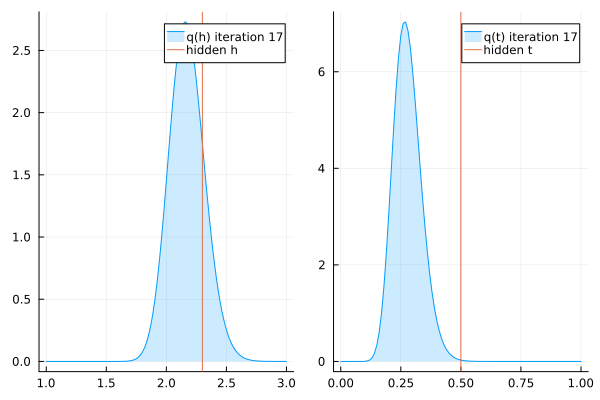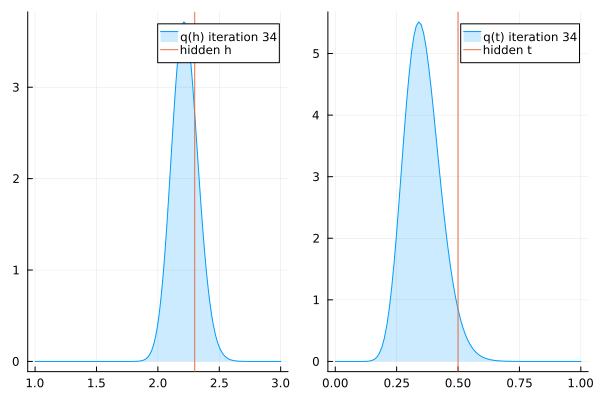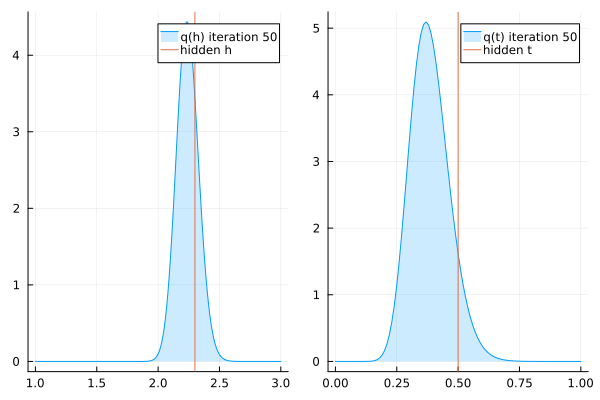
We can see that the inference results are able to recover the actual value of hidden h that has been used to generate the synthetic dataset. In conclusion, this example demonstrates that by integrating deterministic transformations within the logpdf function of a stochastic node, we can bypass the limitations of NodeFunctionRuleFallback in handling deterministic nodes.